Assay resolution governs the transfer of molecular dependence
Abstract
Background. Separate molecular assays retain within-assay coexpression when cross-modal pairing is unavailable. We ask which aspects of this structure support RNA–protein dependence prediction from a paired reference.
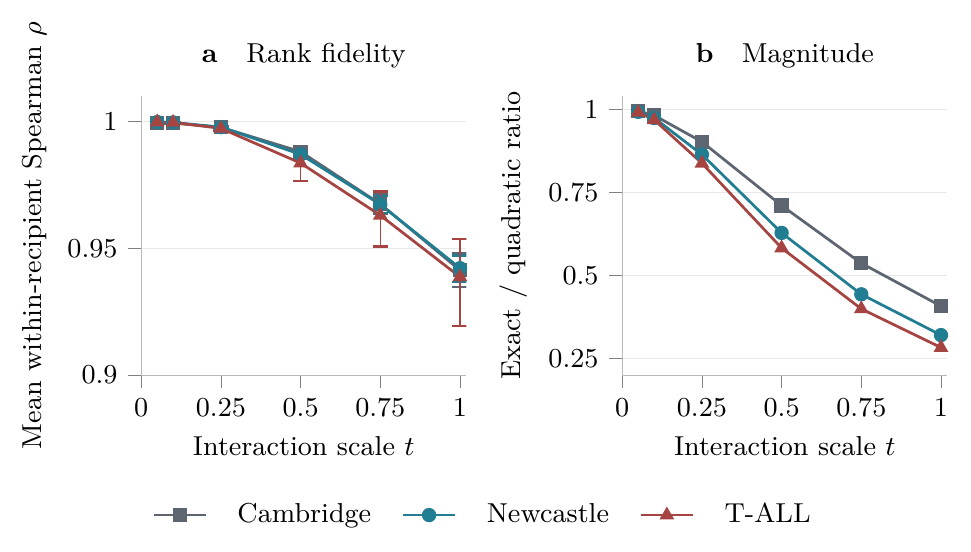
Results. We derive the sharp identified range and minimax predictor for a binary association given a fixed fine-scale interaction and within-assay moment constraints that determine the queried frequencies. The result applies directly when all individual marker frequencies are known; the case with only the two queried frequencies has a closed form. An exact response identity yields a local query-ranking rule that requires no recipient pairings. At the fitted interaction strength, its mean within-recipient Spearman correlation with exact model discrepancy was 0.939–0.942 across cohorts. In retrospective analyses of 24 Cambridge donors, 56 Newcastle donors, and 15 patients with pediatric T-cell acute lymphoblastic leukemia (T-ALL), covariance-preserving reconstruction retained 91–97% of the improvement from full assay patterns over individual marker frequencies. Recipient-specific coexpression reduced mean deviance by 9.2%, 17.9%, and 46.0% relative to pools of other recipients matched to the same marker frequencies (paired donor-bootstrap 95% intervals, 2.3–15.6%, 12.6–23.0%, and 35.2–55.8%). Those pools contained 14–55 times more cells. The response rule concentrated 85–90% of the observed net improvement into 27 of 81 marker pairs and outperformed ranking by direct source-interaction strength in Newcastle and T-ALL.
Conclusions. Recipient coexpression supports dependence predictions that individual marker frequencies and larger pooled samples do not recover. Reconstructing assay patterns before forming coarse queries preserves this information and identifies relationships that benefit from recipient-specific correction.
Background
Joint single-cell assays reveal how molecular measurements covary within cells. When a new cohort supplies the assays separately, a paired reference can support prediction of the missing joint distribution. The recipient still provides two kinds of information: the frequency of each molecular state and the patterns of states observed together within each assay. These are different constraints on the cross-assay prediction.
We derive the complete range of a binary association under arbitrary within-assay moment constraints and a fixed fine interaction. This range applies to the full set of marker frequencies supplied in our benchmark; a closed form is available when only the two queried frequencies are retained. The range gives an attainable worst-case prediction and an error floor that additional observations at the same resolution cannot remove. We then measure the value of within-assay structure while holding the interaction, cells, and recipient marker frequencies fixed. This comparison separates the information retained by each representation from differences between fitted estimators.
A sharp limit at the observed resolution
Let the observed RNA and protein summaries be arbitrary finite collections of within-assay means. They define convex polytopes of complete assay distributions consistent with those summaries. For each pair of assay distributions, matrix scaling gives the unique joint distribution with interaction S and those assay marginals.
The closure of compatible binary query tables is an interval whose endpoints are obtained by minimizing and maximizing the queried joint probability over these polytopes. It is the sharp identified set when all individual marker frequencies are supplied. Complete assay-profile histograms collapse both polytopes to points. Thus the theoretical constraints coincide with the means-only and full-pattern arms of the experiment.
The means-only exponential-family fit selects one member of this set by information projection. The interval records what the supplied frequencies identify without that additional selection. The unique minimax table equalizes the forward Kullback–Leibler loss from the two endpoint tables.
Individual frequencies can all agree
The ambiguity also occurs when every marker's individual frequency is known. Consider two binary RNA markers and one protein marker, coded as Z1, Z2, W ∈ {−1, 1}, each with mean zero. Fix the fine interaction to S = JZ2W, with J ≠ 0. Let the recipient RNA distribution have correlation ρ = E(Z1Z2). Reconstruction gives
Changing ρ from negative to positive reverses the queried RNA–protein association without changing J or any individual marker frequency. Separate RNA profiles reveal ρ; their individual frequencies do not. As ρ ranges over its compatible values, the all-marker interval for Pr(Z1 = 1, W = 1) is [(1 − |tanh J|)/4, (1 + |tanh J|)/4].
How coexpression changes the prediction
For fixed positive assay distributions on finite supports, scale a bilinear interaction as St(x, y) = t x⊤B y, where B is the source interaction matrix and t sets its strength. Let Σx and Σy be the two within-assay covariance matrices. Near independence, the reconstructed cross-assay covariance satisfies
To first order, each predicted RNA–protein covariance sums source interactions weighted by recipient covariances in both assays. A source coefficient therefore need not equal the marginal association observed in a new population.
This local formula is the initial value of an exact finite-strength identity. If st is the score along the fixed-marginal reconstruction, the marginal constraints remove its conditional means and give
The response also predicts which queries are sensitive to replacing recipient coexpression by pooled structure. For a binary query with nonconstant marker frequencies, subtract the queried entries of ΣxBΣy for the recipient and pool, square the difference, and divide by the product of the two marker variances. This is the leading coefficient of twice the KL divergence between their query distributions near independence (Additional file 1). We test whether this score identifies relationships whose empirical prediction improves with recipient-specific reconstruction.
Recipient covariances recover most of the pattern-level gain
The covariance-preserving replacement retained 91.36%, 97.36%, and 95.68% of the loss reduction from individual frequencies to full patterns in Cambridge, Newcastle, and T-ALL, respectively. Full patterns improved further by 4.74% (95% interval, 2.81–6.78%), 2.27% (1.25–3.37%), and 10.35% (7.59–13.74%), improving 22/24, 44/56, and 15/15 people.
Recipient-specific covariance also improved on both pooled controls. Against the source pool, deviance fell by 9.80%, 28.13%, and 60.57% in Cambridge, Newcastle, and T-ALL. Against other recipients in the same cohort, the reductions were 9.15% (95% interval, 2.29–15.57%), 17.94% (12.58–23.00%), and 45.97% (35.24–55.79%), with improvements in 15/24, 42/56, and 14/15 people.
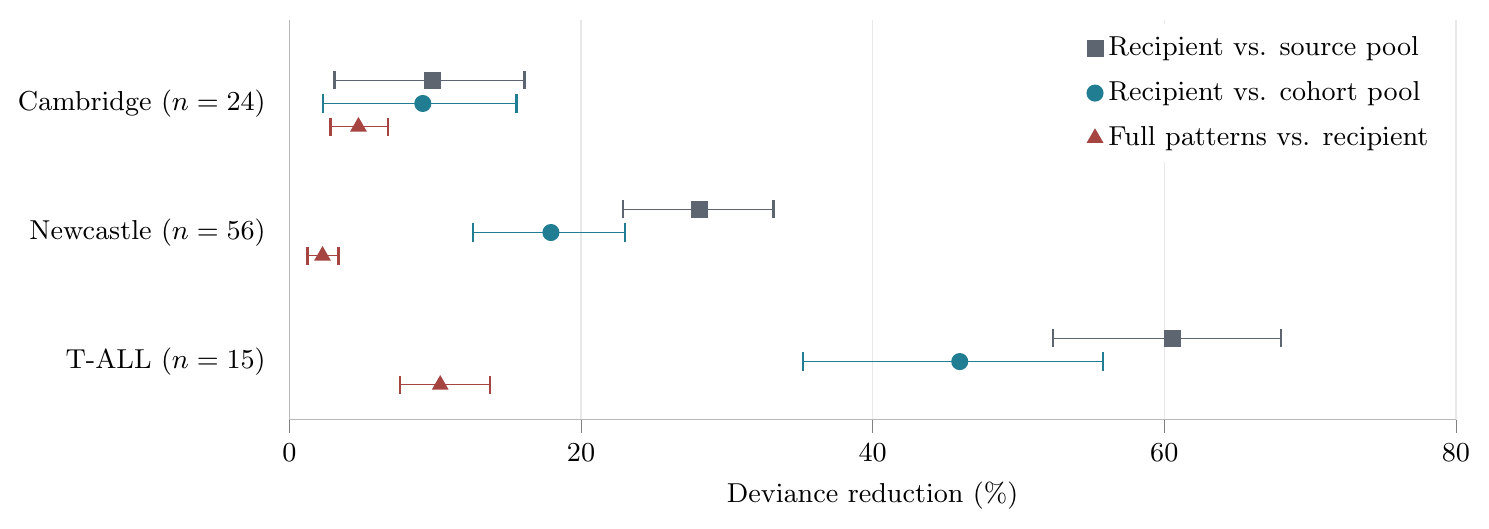
Each recipient supplied 256 adaptation cells per assay, compared with 3,072 source cells or 3,584–14,080 cells in the cohort pool. Matching individual frequencies and using more cells from other people did not recover the recipient-specific gain.
Coexpression prioritizes recipient-specific corrections
The response score concentrated the recipient-specific gain into relatively few relationships. Its top third accounted for 87.0%, 90.1%, and 85.5% of the net deviance reduction in Cambridge, Newcastle, and T-ALL, compared with 85.0%, 60.9%, and 38.5% under direct source-interaction ranking.
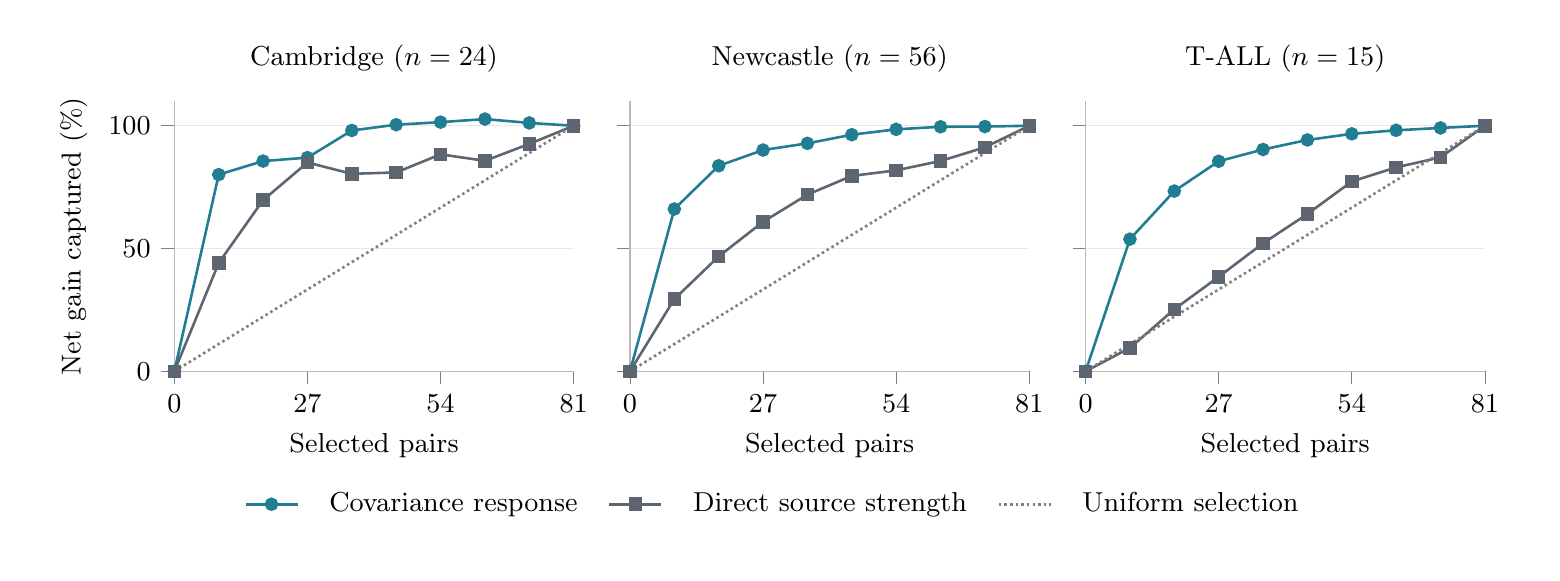
In Newcastle, the mean gain per selected pair was 0.00506 under the response score and 0.00342 under direct ranking; the paired difference was 0.00164 (95% interval, 0.00085–0.00256). In T-ALL the gains were 0.02523 and 0.01135, a difference of 0.01388 (0.00906–0.01925). Both contrasts survived the six-comparison adjustment. Cambridge gave similar gains under the two rankings, 0.00168 and 0.00164 (difference, 0.00004; −0.00077 to 0.00085).
In T-ALL, the three highest cohort-mean scores were for CD7 RNA–CD4 protein, CD4 RNA–CD52 protein, and CD7 RNA–CD52 protein; their mean deviance gains were 0.04513, 0.01245, and 0.04981. The original study used CD4 and CD7 to distinguish T-cell populations and included CD52 in a leukemia expression signature. These corrections concern marker combinations associated with the cohort's cellular heterogeneity.
The response ranking persists at fitted strength
The response coefficient remained closely aligned with exact model discrepancy as the interaction increased from independence to its fitted strength. At t = 1, mean within-recipient Spearman correlations were 0.941 in Cambridge (95% interval, 0.935–0.948), 0.942 in Newcastle (0.937–0.947), and 0.939 in T-ALL (0.919–0.954). The response and exact rankings shared 90.3%, 89.5%, and 89.1% of their top 27 queries. The cohort-aggregate exact discrepancy was 40.8%, 32.1%, and 28.3% of the quadratic approximation.
Discussion
The resolution at which a relationship is reported need not be the resolution at which it should be transferred. A binary RNA–protein table depends on the distribution of finer cellular profiles. Reconstructing those profiles before aggregation allowed one source interaction to predict different recipient associations using measurements made separately within each assay.
The pooled controls distinguish recipient-specific coexpression from generic population structure: more observations from other people did not replace the recipient's own assay patterns.
Limitations
The resolution and query-ranking analyses are retrospective analyses of previously examined recipients from two studies, not new confirmation. Intervals condition on the source fit and fitted pools, omitting their estimation uncertainty, dependence between overlapping cohort pools, and the adaptive research history. The earlier T-ALL model comparison was fixed before count access but did not pass its all-control superiority criterion.
The panel contains nine RNA and nine protein markers, and protein states use donor-wide ranks that include scoring values. Individual scoring-cell marker frequencies are supplied. Two Stephenson recipients have almost no counts across the protein panel and were retained. The task is fixed-margin dependence prediction, not missing-modality imputation without target assay values. The results do not isolate within-cell-type regulation or establish molecular binding, causal effects, or clinical utility.
The identified interval assumes a known transferable interaction, finite assay supports, and exact recipient summaries. Its all-marker endpoints require global optimization over the corresponding marginal polytopes; only the two-frequency case has the closed form reported here. The examples establish ambiguity, not its biological magnitude. Query-wise minimax predictions need not form a coherent multivariate law. Interaction drift, sampling error, and coarsening ambiguity remain distinct.
We tested one maximum-entropy replacement, which preserves fitted means and covariances but can induce higher-order correlations. The retained gain is descriptive, not causal mediation. The exact response identity holds at finite strength, but the query score is its local coefficient; at t = 1, the quadratic approximation exceeded the exact model discrepancy. The score predicts model discrepancy, not error against an arbitrary biological population. The query-ranking advantage over direct source strength was unresolved in Cambridge. Prioritization requires the full measured panel and does not establish savings from measuring fewer markers. Sorting and cell mixtures can contribute to the observed coexpression.
Reconstruction, noncollapsibility, and minimax KL prediction have established foundations. The theory concerns the resolution-dependent identified set; the experiments establish an information advantage, not a superior cost learner. The CHAMPOLLION comparator uses its no-prior objective with a common recipient adapter, not its complete published workflow.
Conclusions
Within-assay cellular patterns improved cross-cohort RNA–protein dependence prediction with the source interaction held fixed. Recipient-specific covariances retained most of this gain and outperformed source and cohort pools matched to the same marker frequencies. Full patterns improved further in each cohort. Separately measured recipient coexpression can therefore support molecular predictions that individual frequencies and cohort averages do not recover.
Availability of data and materials
Source data are available through the accessions in Additional file 1, including GSE248287 for the T-ALL cohort. The original benchmark's analysis plans, MIT-licensed software, and study records are available in the v2.0.4 release. The resolution and query-ranking analyses are subsequent work and are not included in that release. Additional file 1 documents their protocols and computational verification. Raw matrices are not redistributed.